The AI Workflow for Professional Data Analysis
Demystifying the exact, step-by-step operational pipeline that elite analysts use to extract strategic business intelligence using frontier AI models.
There is a pervasive misconception among executives and junior analysts alike regarding how artificial intelligence actually functions in a professional data environment. The popular imagination pictures a monolithic black box: you upload a massive, disorganized CSV file, type "tell me how to increase revenue," and the AI magically prints out a million-dollar business strategy. In reality, attempting to use AI in this manner produces nothing but generic hallucinations and statistically invalid noise.
Professional data analysis is a rigorous, highly structured discipline, and integrating AI does not bypass that rigor; it amplifies it. An AI model like GPT-6 Astra or Claude Fable 5.1 is an incredibly powerful computational engine, but it is entirely devoid of business context. It does not know your company's risk tolerance, it does not understand your nuanced industry vocabulary, and it cannot independently determine which variables are actually confounding.
To extract genuine, board-ready insights, you must adopt a strict operational pipeline. You must learn how to securely ingest data, direct exploratory analysis, formulate rigid statistical hypotheses, and translate the resulting mathematical variance into strategic human language. This article deconstructs that exact five-step workflow used by top-tier data professionals.
Data Ingestion and Context Setting
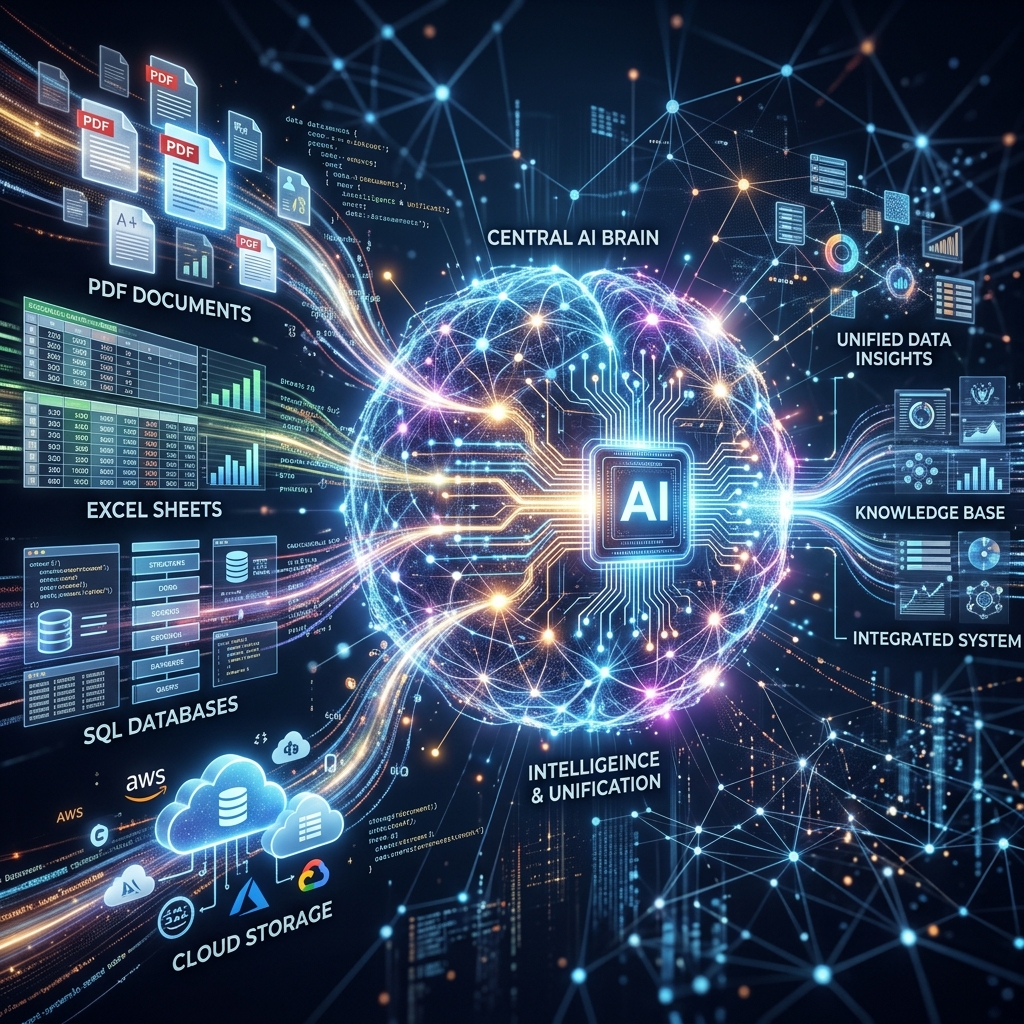
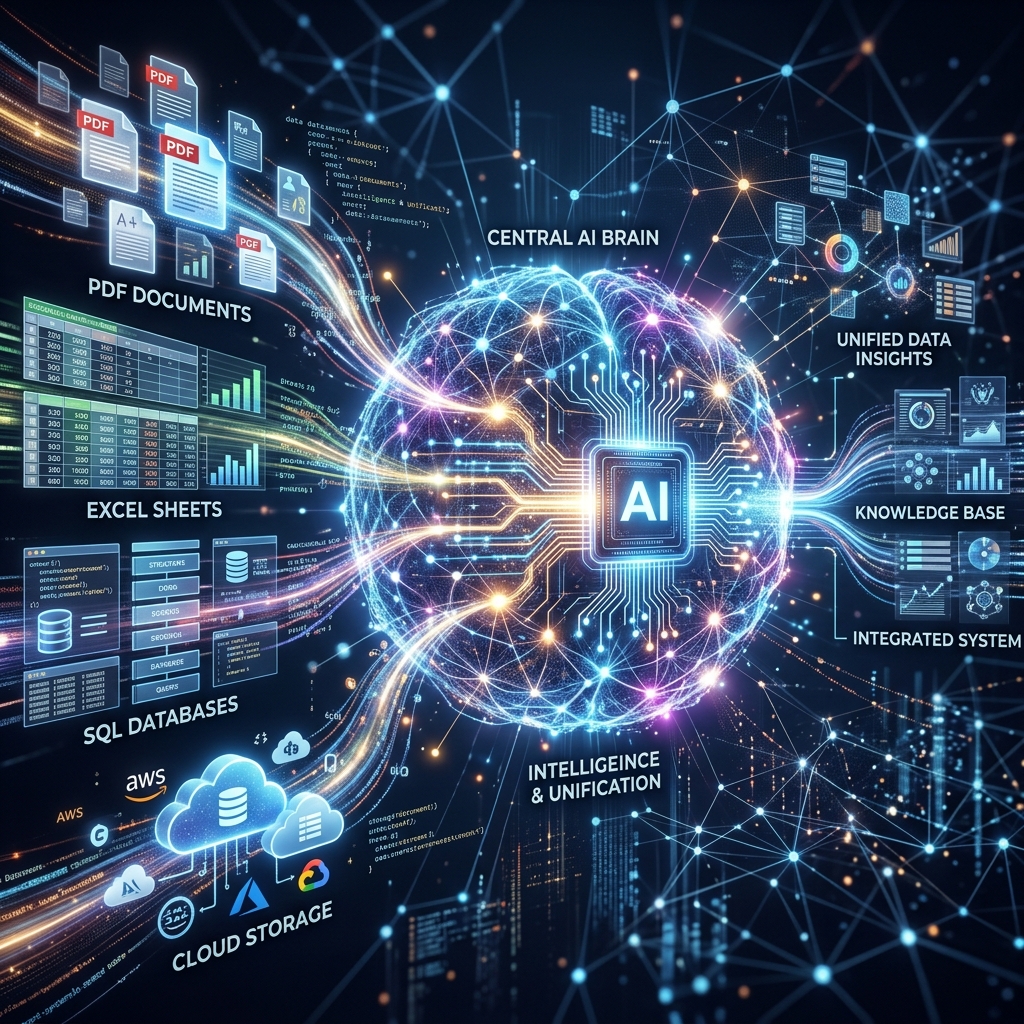
The workflow begins long before you ask the AI a single analytical question. The first and most critical phase is secure data ingestion and semantic context setting. If you feed an AI garbage data devoid of context, you will receive garbage insights wrapped in very articulate sentences.
Before uploading any dataset to a frontier model, a professional analyst must sanitize the data. This involves stripping out all Personally Identifiable Information (PII) such as customer names, email addresses, and raw credit card numbers to comply with GDPR and internal security protocols. You provide the AI with randomized unique identifiers (UUIDs) instead.
Once the data is securely sanitized, you must establish the semantic context. You cannot simply upload a table called `users_v2` and expect the AI to understand it. You must provide a comprehensive data dictionary. You instruct the AI: "You are operating as a Senior Data Scientist for a B2B logistics company. I am providing a table named `shipments`. The `transit_time` column is measured in hours, excluding weekends. The `status_code` column maps to the following dictionary: 1=Pending, 2=In-Transit, 3=Delivered, 4=Exception."
By explicitly defining the rules of the data ecosystem, you prevent the AI from making catastrophic assumptions (for example, assuming `transit_time` is measured in days rather than hours). This upfront investment in context-setting is the foundational bedrock that ensures all subsequent mathematical operations are grounded in the actual reality of your specific business.
Exploratory Data Analysis (EDA)
Once the context is locked, the next phase is Exploratory Data Analysis (EDA). Historically, this was a tedious process where the analyst would spend hours writing boilerplate Python pandas code to check for null values, plot basic histograms, and calculate mean and median distributions just to understand the basic shape of the dataset.
AI accelerates this phase exponentially. Instead of writing the code manually, you delegate the mechanical exploration to the model. You prompt the AI: "Perform a comprehensive exploratory data analysis on this dataset. Identify the percentage of missing values per column. Generate summary statistics for all numerical variables. Output a correlation matrix highlighting any variables with a Pearson correlation coefficient greater than 0.6. Identify any statistical outliers in the `revenue` column using the interquartile range (IQR) method."
Within seconds, the AI will execute the underlying Python scripts and return a comprehensive summary. This is where the human analyst's expertise becomes vital. The AI might flag a specific cluster of high-revenue transactions as "statistical outliers" because they deviate from the norm. The human analyst, possessing business context, realizes that those aren't errors—those are the enterprise-tier clients.
During the EDA phase, the AI acts as a high-speed scanner, surfacing anomalies, distributions, and baseline correlations. The human analyst reviews this scan, decides which anomalies are data errors to be cleaned and which are genuine business phenomena worth investigating further. This collaborative loop rapidly narrows the focus of the analysis from a broad dataset down to a few highly specific areas of interest.
Hypothesis Testing and Statistical Rigor
The transition from EDA to hypothesis testing is the threshold between amateur observation and professional analytics. An amateur looks at a chart showing that sales were higher on Tuesday than Monday and states it as a fact. A professional analyst formulates a hypothesis and tests it to ensure the difference isn't just random variance.
Armed with the insights from the EDA phase, you formulate a rigid business hypothesis. For example: "Implementing the new onboarding flow decreased the average time-to-first-purchase." You do not ask the AI to simply "prove this." You ask it to execute the specific statistical test required to validate it.
Your prompt must be mathematically precise: "Segment the users into a control group (old flow) and an experimental group (new flow). Perform an independent two-sample t-test to compare the mean `time_to_purchase` between the two groups. Set the alpha level at 0.05. Check for the assumption of equal variances using Levene's test before proceeding. Output the final p-value and state whether we reject the null hypothesis."
By dictating the specific statistical methodology, you prevent the AI from taking mathematical shortcuts. The AI acts as your rapid calculator, running the t-test and returning the p-value instantly. If the p-value is 0.02, you know the result is statistically significant. If the AI suggests running a linear regression to predict future outcomes, you, as the human overseer, must verify that the data actually meets the strict assumptions of linearity and homoscedasticity before accepting the model's predictions as truth.
Visual Storytelling and Dashboarding
Once the hypothesis has been mathematically validated, the data must be transformed into a visual format that human beings can instantly comprehend. A p-value of 0.02 means nothing to a Chief Marketing Officer. They need to see the impact visualized clearly.
Historically, building complex, interactive visualizations required deep expertise in libraries like D3.js or extensive clicking within Tableau. In the AI workflow, you simply describe the visual intent. However, you must describe it with design constraints.
You prompt the model: "Generate the Python Plotly code to create a dual-axis line chart. The primary Y-axis should show total revenue in USD, colored in a solid blue (#1E3A8A). The secondary Y-axis should show the churn rate percentage, colored in a dashed red (#DC2626). The X-axis should be aggregated by month. Remove all background grid lines to maintain a minimalist, corporate aesthetic. Add a clear, declarative title stating the key takeaway, not just a description of the axes."
The AI generates the exact charting code required. By dictating the color hex codes and demanding a declarative title, you ensure the visualization adheres to professional design standards and tells a specific story. You are not just rendering data; you are guiding the viewer's eye to the exact intersection of variables that proves your strategic point. The AI handles the complex syntax of the charting library, allowing you to focus entirely on the narrative impact of the visual.
Executive Translation
The final, and arguably most crucial, step in the professional workflow is executive translation. Data is only valuable if it drives a business decision. The greatest statistical model in the world is useless if the executive team cannot understand its implications.
The human analyst must take the validated statistics and the clean visualizations and synthesize them into a strategic narrative. You can use a model like Claude Fable 5.1 to assist in drafting this final memo. You provide it with your findings and prompt: "Act as a Chief Data Officer. Translate these statistical findings into a one-page executive memo for the CEO. Remove all academic statistical jargon (do not mention p-values or heteroscedasticity). Focus entirely on the financial impact, the specific operational bottleneck we identified, and outline three actionable recommendations based on the data."
The AI will draft a highly polished, commercially focused memo. However, the human analyst must review this draft meticulously, ensuring the tone matches the company culture and that the strategic recommendations are practically feasible within the current operational constraints.
This five-step workflow—Ingestion, EDA, Hypothesis Testing, Visualization, and Translation—represents the modern gold standard of data analysis. The AI acts as your mechanical executor at every stage, but the human remains the indispensable pilot, providing the context, enforcing the mathematical rigor, and driving the ultimate business strategy. Explore our premium case studies to see this exact workflow applied to real-world datasets across multiple industries.