GPT-6 Astra for Data Analytics
How autonomous AI is shifting the role of the data analyst from writing boilerplate SQL to driving high-level statistical strategy and business intelligence.
For decades, the day-to-day reality of a data analyst has been characterized by friction. Before any actual business intelligence could be extracted, an analyst had to spend hours navigating inconsistent database schemas, writing verbose SQL joins, cleaning malformed CSV files in Python or Excel, and building fragile data pipelines. The actual analysis—the critical thinking that drives business value—often comprised less than twenty percent of the workflow. The rest was mechanical data wrangling.
GPT-6 Astra radically alters this equation. With its deep reasoning capabilities and robust execution environment, Astra is not just a tool that can write a `SELECT` statement. It operates as a highly capable junior data scientist that can ingest raw datasets, autonomously identify and clean anomalies, write complex aggregations, execute Python scripts to perform statistical significance testing, and output production-ready visualizations. It transforms the highly technical barrier of entry into a conversational interface.
However, delegating analytics to an AI introduces entirely new categories of risk. When a human makes a math error, it is usually localized. When an AI hallucinate a fundamentally flawed statistical assumption across millions of rows of data, it can quietly misguide an entire corporate strategy. This article deconstructs how to safely and effectively use GPT-6 Astra for professional data analytics, separating the hype from the practical reality of modern AI data workflows.
Automating the Data Pipeline
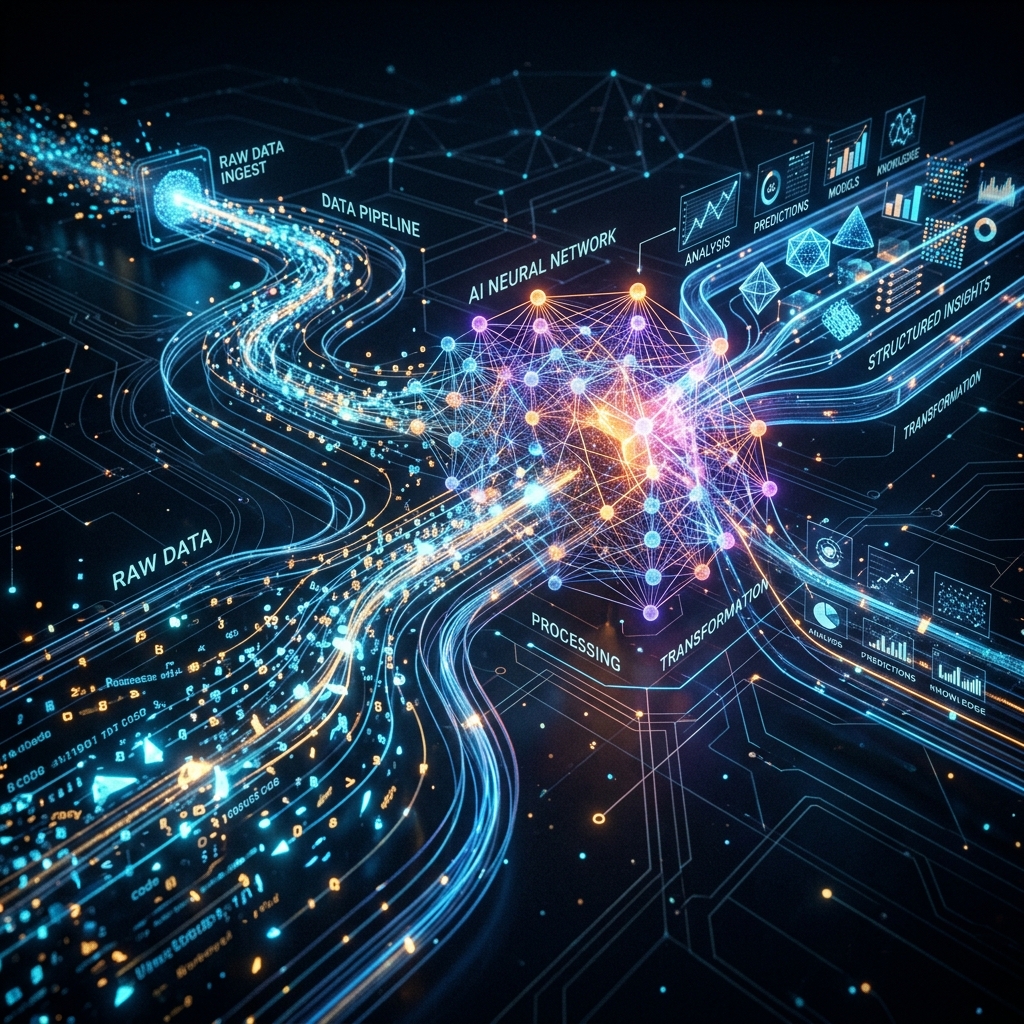
The foundation of all meaningful analytics is clean, reliable data. Historically, the Extract, Transform, and Load (ETL) process has been a highly specialized engineering discipline. Data arrives from disparate sources—Stripe for payments, Salesforce for CRM, Google Analytics for web traffic—and must be normalized into a single data warehouse. This normalization process is notoriously brittle, constantly breaking whenever a third-party API changes a field name or a user inputs a localized date format.
GPT-6 Astra drastically accelerates pipeline construction by operating as a semantic bridge. Because Astra inherently understands the semantic meaning of data, it does not require hardcoded, rigid mapping rules. You can provide Astra with a messy export from an antiquated legacy system and instruct it: "Normalize this dataset. Convert all European date formats to ISO 8601, standardize all currency values to USD using historical exchange rates, and merge the 'ClientName' column with the 'Company' column from the CRM dataset using fuzzy string matching."
Astra will autonomously write and execute the Python Pandas scripts required to perform these transformations. More importantly, it can handle edge cases dynamically. If it encounters a corrupted row, it can be instructed to flag it, quarantine it, or attempt a probabilistic repair based on surrounding data context. This shifts the ETL paradigm from "brittle, rule-based execution" to "resilient, semantic interpretation."
However, this autonomy requires strict oversight. Automated data cleaning can sometimes be too aggressive, dropping rows that contain vital, albeit irregular, business information. The professional workflow demands that Astra outputs an explicit transformation log—a detailed record of exactly which rows were altered, dropped, or merged. The human analyst must review this log to ensure that the AI's cleaning logic has not inadvertently introduced systemic bias into the foundational dataset before any downstream analysis occurs.
Continue reading with Premium
Unlock the complete guide to Astra's data analytics workflows, practical SQL/Python prompts, advanced statistical modeling, and the exact step-by-step professional process.
Upgrade to Premium →